Build interactive PDF text extraction from Amazon S3
AWS Machine Learning published a guide detailing how to create a server that extracts text from PDF files stored in Amazon S3 in real time. The tutorial explains a protocol-based approach that enables programmatic access to document contents. Additionally, it compares this method against Amazon Textract to help developers choose the right tool for their workload.
Key Takeaways
- A new guide from AWS Machine Learning demonstrates how to build a server that extracts text from PDF files located in Amazon S3 in real time.
The tutorial outlines the system architecture and guides readers through setting up the server to perform interactive document queries using a protocol-based approach for programmatic document access.
- Comparing a protocol-based server against existing solutions like Amazon Textract helps practitioners select the most suitable workflow for their specific data extraction needs.
Developers can construct a server to extract text from PDF files stored in Amazon S3 in real time.
- The post compares this custom server implementation against Amazon Textract to guide tool selection.
- To assist developers in evaluating document processing options, the resource evaluates this custom setup alongside Amazon Textract.
- The protocol-based system delivers programmatic document access for running interactive queries.
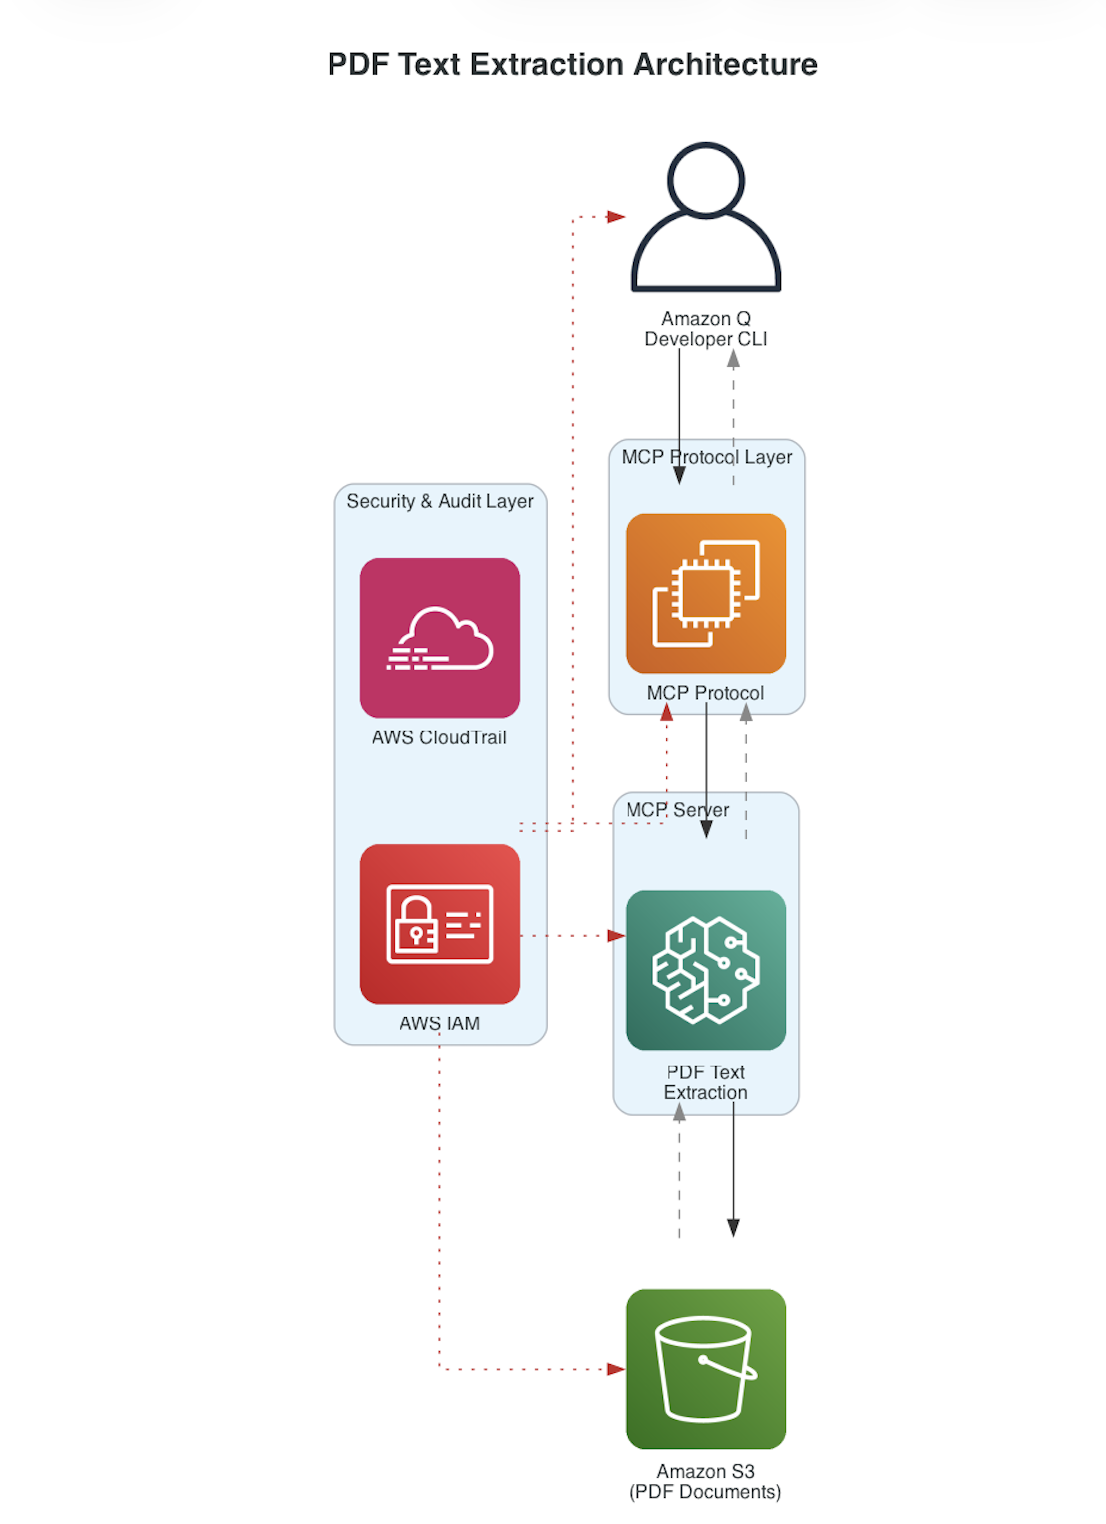
A new guide from AWS Machine Learning demonstrates how to build a server that extracts text from PDF files located in Amazon S3 in real time. The tutorial outlines the system architecture and guides readers through setting up the server to perform interactive document queries using a protocol-based approach for programmatic document access. To assist developers in evaluating document processing options, the resource evaluates this custom setup alongside Amazon Textract.
Comparing a protocol-based server against existing solutions like Amazon Textract helps practitioners select the most suitable workflow for their specific data extraction needs. Developers can construct a server to extract text from PDF files stored in Amazon S3 in real time. The protocol-based system delivers programmatic document access for running interactive queries.
For more details please read the original article at AWS Machine Learning.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.