Debugging production agents with Amazon Bedrock AgentCore Observability
AWS Machine Learning released a guide on identifying and fixing errors in production AI agents using "Amazon Bedrock AgentCore Observability". The publication details methods for diagnosing operational issues through built-in traces and performance metrics. As the first entry in a two-part guide, this article focuses on resolving specific problems like infinite loops and tool invocation errors.
Key Takeaways
- AWS Machine Learning has outlined strategies for troubleshooting autonomous AI systems in production using "Amazon Bedrock AgentCore Observability".
The tutorial explains how developers can leverage built-in monitoring tools to track system execution paths and detect standard failure modes.
- By reviewing trace logs and performance metrics, operators can pinpoint exact points of failure during complex interactions.
The guide introduces step-by-step procedures to resolve frequent runtime problems, including infinite loops and tool invocation errors.
- As the initial installment of a two-part series, it focuses on diagnosis and error remediation, while the upcoming second part will address memory management and performance tuning.
Understanding these debugging workflows helps developers maintain reliable autonomous workflows in real-world deployments.
- Developers can inspect production agent behavior by using built-in traces and system metrics.
The guide provides structured troubleshooting workflows to address tool invocation failures and infinite loops.
- This publication serves as "Part 1 of a two-part series" focusing on resolving operational agent errors.
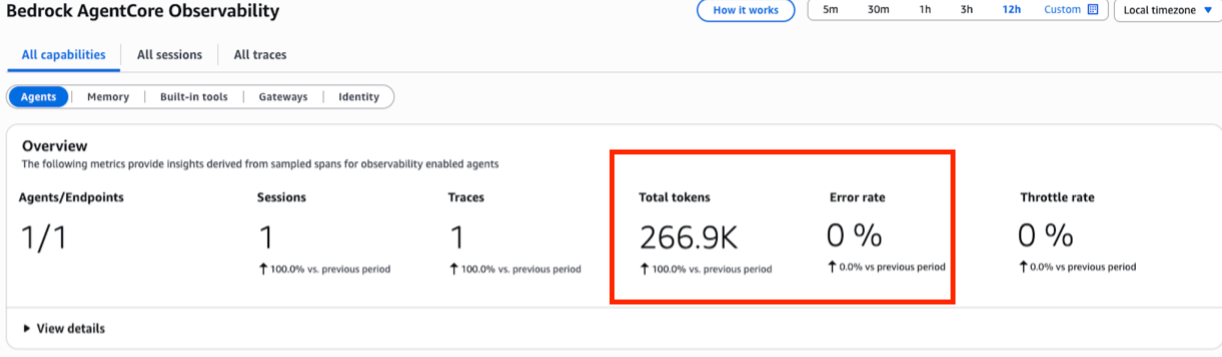
AWS Machine Learning has outlined strategies for troubleshooting autonomous AI systems in production using "Amazon Bedrock AgentCore Observability". The tutorial explains how developers can leverage built-in monitoring tools to track system execution paths and detect standard failure modes. By reviewing trace logs and performance metrics, operators can pinpoint exact points of failure during complex interactions.
The guide introduces step-by-step procedures to resolve frequent runtime problems, including infinite loops and tool invocation errors. As the initial installment of a two-part series, it focuses on diagnosis and error remediation, while the upcoming second part will address memory management and performance tuning. Understanding these debugging workflows helps developers maintain reliable autonomous workflows in real-world deployments.
Developers can inspect production agent behavior by using built-in traces and system metrics. The guide provides structured troubleshooting workflows to address tool invocation failures and infinite loops. This publication serves as "Part 1 of a two-part series" focusing on resolving operational agent errors.
For more details please read the original article at AWS Machine Learning.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.