Enhancing enterprise inference on Amazon SageMaker HyperPod with data capture, Hugging Face, NVMe, and Route 53 integration
AWS Machine Learning has outlined five new features for enterprise inference on Amazon SageMaker HyperPod. These additions include multi-tier data capture, direct deployment from Hugging Face Hub, and local NVMe model loading to accelerate cold starts. Additionally, the service now supports automated Route 53 DNS integration alongside pod-level IAM permissions using custom service accounts.
Key Takeaways
- Amazon SageMaker HyperPod has introduced five key capabilities aimed at improving enterprise inference workflows.
Organizations using the platform can now leverage multi-tier data capture, which helps teams audit system activity and gather data for model improvement.
- Security and access control are also expanded through pod-level IAM configurations that utilize custom service accounts, giving administrators more granular governance over their workloads.
To streamline deployment and reduce performance bottlenecks, SageMaker HyperPod supports direct deployment from the Hugging Face Hub.
- Loading models locally via NVMe storage decreases latency during cold starts, allowing applications to spin up faster.
Furthermore, automated Route 53 DNS integration allows teams to establish custom domain names easily for their inference endpoints.
- Amazon SageMaker HyperPod inference now supports five new capabilities designed for enterprise deployment.
Direct deployment from Hugging Face Hub and local NVMe model loading help streamline model setups and speed up cold starts.
- Organizations can utilize multi-tier data capture to support auditing efforts and drive ongoing model improvement.
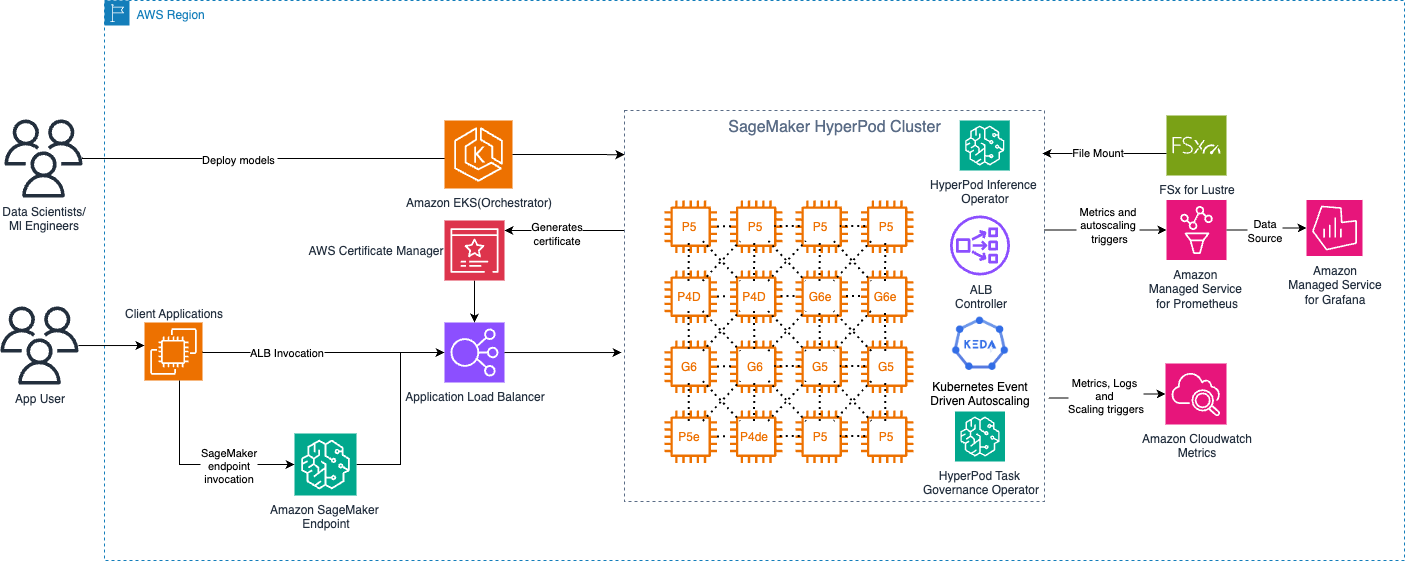
Amazon SageMaker HyperPod has introduced five key capabilities aimed at improving enterprise inference workflows. Organizations using the platform can now leverage multi-tier data capture, which helps teams audit system activity and gather data for model improvement. Security and access control are also expanded through pod-level IAM configurations that utilize custom service accounts, giving administrators more granular governance over their workloads.
To streamline deployment and reduce performance bottlenecks, SageMaker HyperPod supports direct deployment from the Hugging Face Hub. Loading models locally via NVMe storage decreases latency during cold starts, allowing applications to spin up faster. Furthermore, automated Route 53 DNS integration allows teams to establish custom domain names easily for their inference endpoints.
Amazon SageMaker HyperPod inference now supports five new capabilities designed for enterprise deployment. Direct deployment from Hugging Face Hub and local NVMe model loading help streamline model setups and speed up cold starts. Organizations can utilize multi-tier data capture to support auditing efforts and drive ongoing model improvement.
For more details please read the original article at AWS Machine Learning.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.