Evaluating AI Agents: A production blueprint with Strands and AgentCore
Motorway collaborated with AWS to construct an end-to-end evaluation system for artificial intelligence agents using the Strands Agents SDK and Amazon Bedrock AgentCore. The implemented system improved output accuracy while dramatically speeding up issue detection. The original article outlines how developers can replicate this evaluation framework for their own systems.
Key Takeaways
- Motorway worked alongside AWS to establish an end-to-end evaluation framework designed specifically for artificial intelligence agents.
By leveraging the Strands Agents SDK alongside Amazon Bedrock AgentCore, a managed platform built for operating AI agents at scale, the teams established a production blueprint to measure performance and address errors.
- Additionally, the system reduced the time required to detect issues from a few hours down to a few minutes, illustrating how robust evaluation pipelines enhance reliability in real-world agent deployments.
Motorway and AWS built an end-to-end evaluation pipeline for artificial intelligence agents.
- The new pipeline reduced incorrect results from 1 in 8 queries to 1 in 50.
Issue detection time was cut from a few hours to a few minutes.
- The system combines the Strands Agents SDK with Amazon Bedrock AgentCore to manage agents at scale.
- The deployment delivered significant operational gains by lowering the frequency of incorrect outputs from 1 in 8 queries to 1 in 50.
Stats & Key Facts
- #The deployment delivered significant operational gains by lowering the frequency of incorrect outputs from 1 in 8 queries to 1 in 50.
- #The new pipeline reduced incorrect results from 1 in 8 queries to 1 in 50.
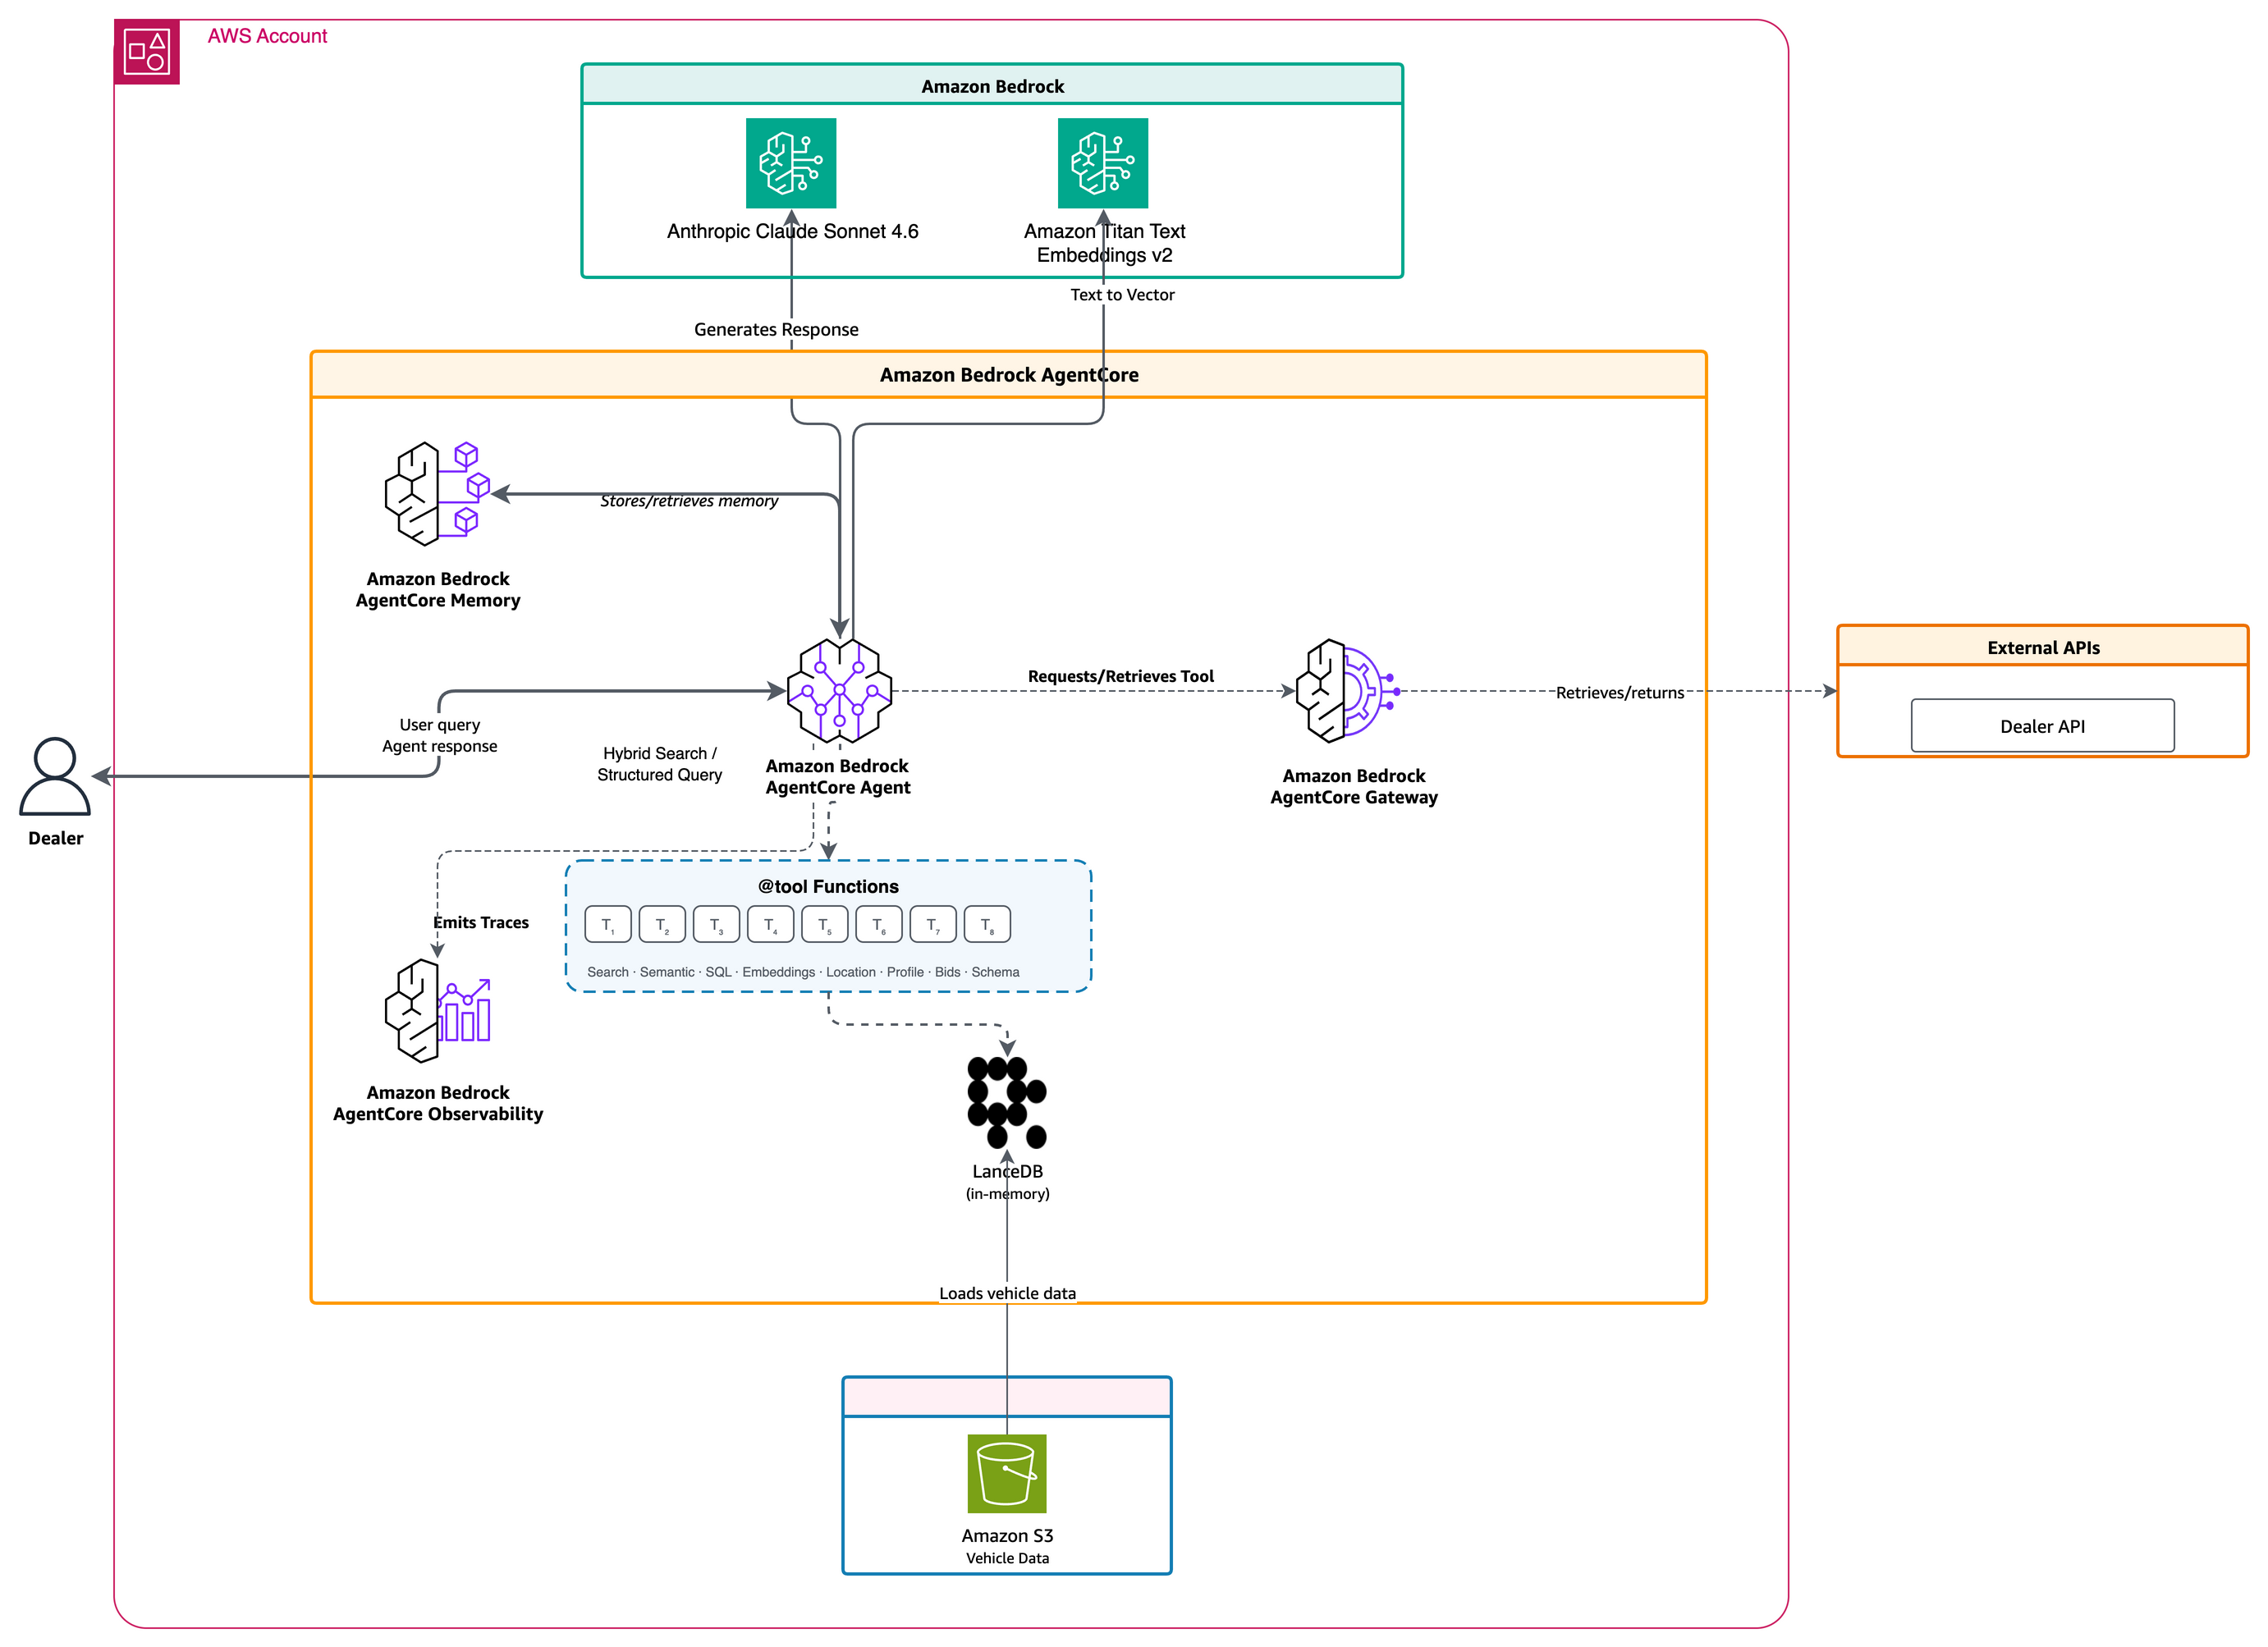
Motorway worked alongside AWS to establish an end-to-end evaluation framework designed specifically for artificial intelligence agents. By leveraging the Strands Agents SDK alongside Amazon Bedrock AgentCore, a managed platform built for operating AI agents at scale, the teams established a production blueprint to measure performance and address errors. The deployment delivered significant operational gains by lowering the frequency of incorrect outputs from 1 in 8 queries to 1 in 50.
Additionally, the system reduced the time required to detect issues from a few hours down to a few minutes, illustrating how robust evaluation pipelines enhance reliability in real-world agent deployments. Motorway and AWS built an end-to-end evaluation pipeline for artificial intelligence agents. The new pipeline reduced incorrect results from 1 in 8 queries to 1 in 50.
For more details please read the original article at AWS Machine Learning.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.