Exploring self-distilled reasoning for supervised fine-tuning with Amazon Nova
AWS Machine Learning published an exploration of Self-Distilled Reasoning (SDR) using Amazon Nova. The technique addresses the reasoning suppression problem by generating thinking tokens for datasets lacking reasoning traces during SFT customization. The approach was validated across three benchmarks alongside practical recommendations.
Key Takeaways
- AWS Machine Learning introduced Self-Distilled Reasoning (SDR) to improve supervised fine-tuning (SFT) customization with Amazon Nova.
The post identifies a reasoning suppression problem that occurs when target datasets do not contain explicit reasoning traces.
- The effectiveness of the Self-Distilled Reasoning framework was validated across three distinct benchmarks.
In addition to performance evaluations, the publication provides practical recommendations for practitioners who customize models using datasets without built-in reasoning steps.
- Self-Distilled Reasoning (SDR) creates thinking tokens for datasets that lack explicit reasoning traces during SFT customization.
The SDR method addresses the reasoning suppression problem when customizing models using Amazon Nova.
- AWS Machine Learning validated the effectiveness of the SDR approach across three distinct benchmarks.
- SDR solves this issue by generating thinking tokens to support model learning.
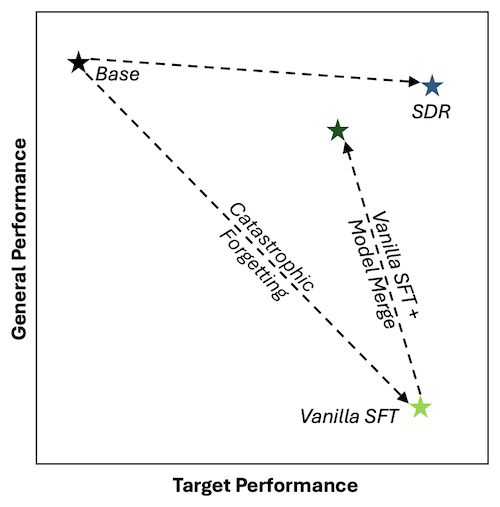
AWS Machine Learning introduced Self-Distilled Reasoning (SDR) to improve supervised fine-tuning (SFT) customization with Amazon Nova. The post identifies a reasoning suppression problem that occurs when target datasets do not contain explicit reasoning traces. SDR solves this issue by generating thinking tokens to support model learning.
The effectiveness of the Self-Distilled Reasoning framework was validated across three distinct benchmarks. In addition to performance evaluations, the publication provides practical recommendations for practitioners who customize models using datasets without built-in reasoning steps. Self-Distilled Reasoning (SDR) creates thinking tokens for datasets that lack explicit reasoning traces during SFT customization.
For more details please read the original article at AWS Machine Learning.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.