From PDFs to insights: Architecting an intelligent document processing pipeline with AWS generative AI services
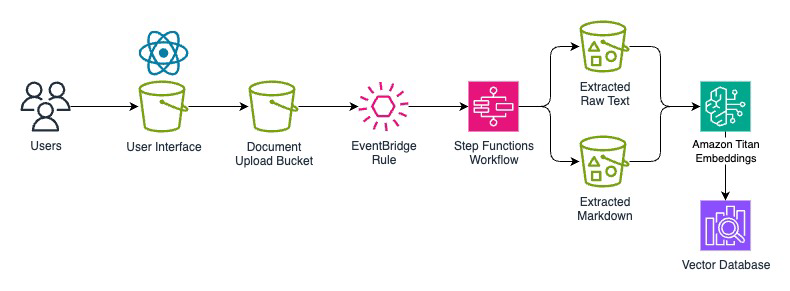
This AWS Machine Learning Blog post describes how to build a cost-effective and scalable intelligent document processing pipeline on AWS, powered by Amazon Bedrock. It shows how Amazon Bedrock Data Automation (BDA) extracts and analyzes document content, while a Strands Agent hosted on Amazon Bedrock AgentCore Runtime coordinates specialized processing tasks, and Amazon Bedrock Knowledge Bases provide contextual understanding across multiple documents. The post argues that combining these capabilities in one architecture lets organizations transform document workflows with minimal development effort.
Read the full story at AWS Machine Learning
This publisher only syndicates a short excerpt by RSS. The full article, with all the detail, quotes, and context, lives on their site.
Open original articleContinue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.