From prototype to production: Engineering agents with Agent DLC
The publisher noted that software agents often stall between prototype demos and production releases when teams lack repeatable measurement tools. Without reliable evaluation systems, developers cannot accurately judge agent quality or confirm whether recent changes helped.
Key Takeaways
- In an article titled "From prototype to production: Engineering agents with Agent DLC" published on November 12, 2026, AWS Machine Learning addressed common hurdles in agent deployment.
The publication noted that projects often stall between demonstration and full release.
- This slowdown occurs because engineering teams frequently lack a standardized, repeatable approach to evaluate how well an agent performs.
The inability to measure quality makes it difficult for teams to assess whether recent system updates resulted in positive changes.
- Building reliable evaluation frameworks alongside agent software helps ensure that code modifications lead to verifiable progress.
Without clear metrics to track improvements, agent development risks getting stuck in an endless prototyping cycle.
- Artificial intelligence agents often stall between initial prototype demos and final production releases.
Teams struggle to move past the demonstration phase when they lack repeatable methods to measure agent performance.
- Without proper evaluation techniques, engineering teams cannot determine if recent updates improved an agent.
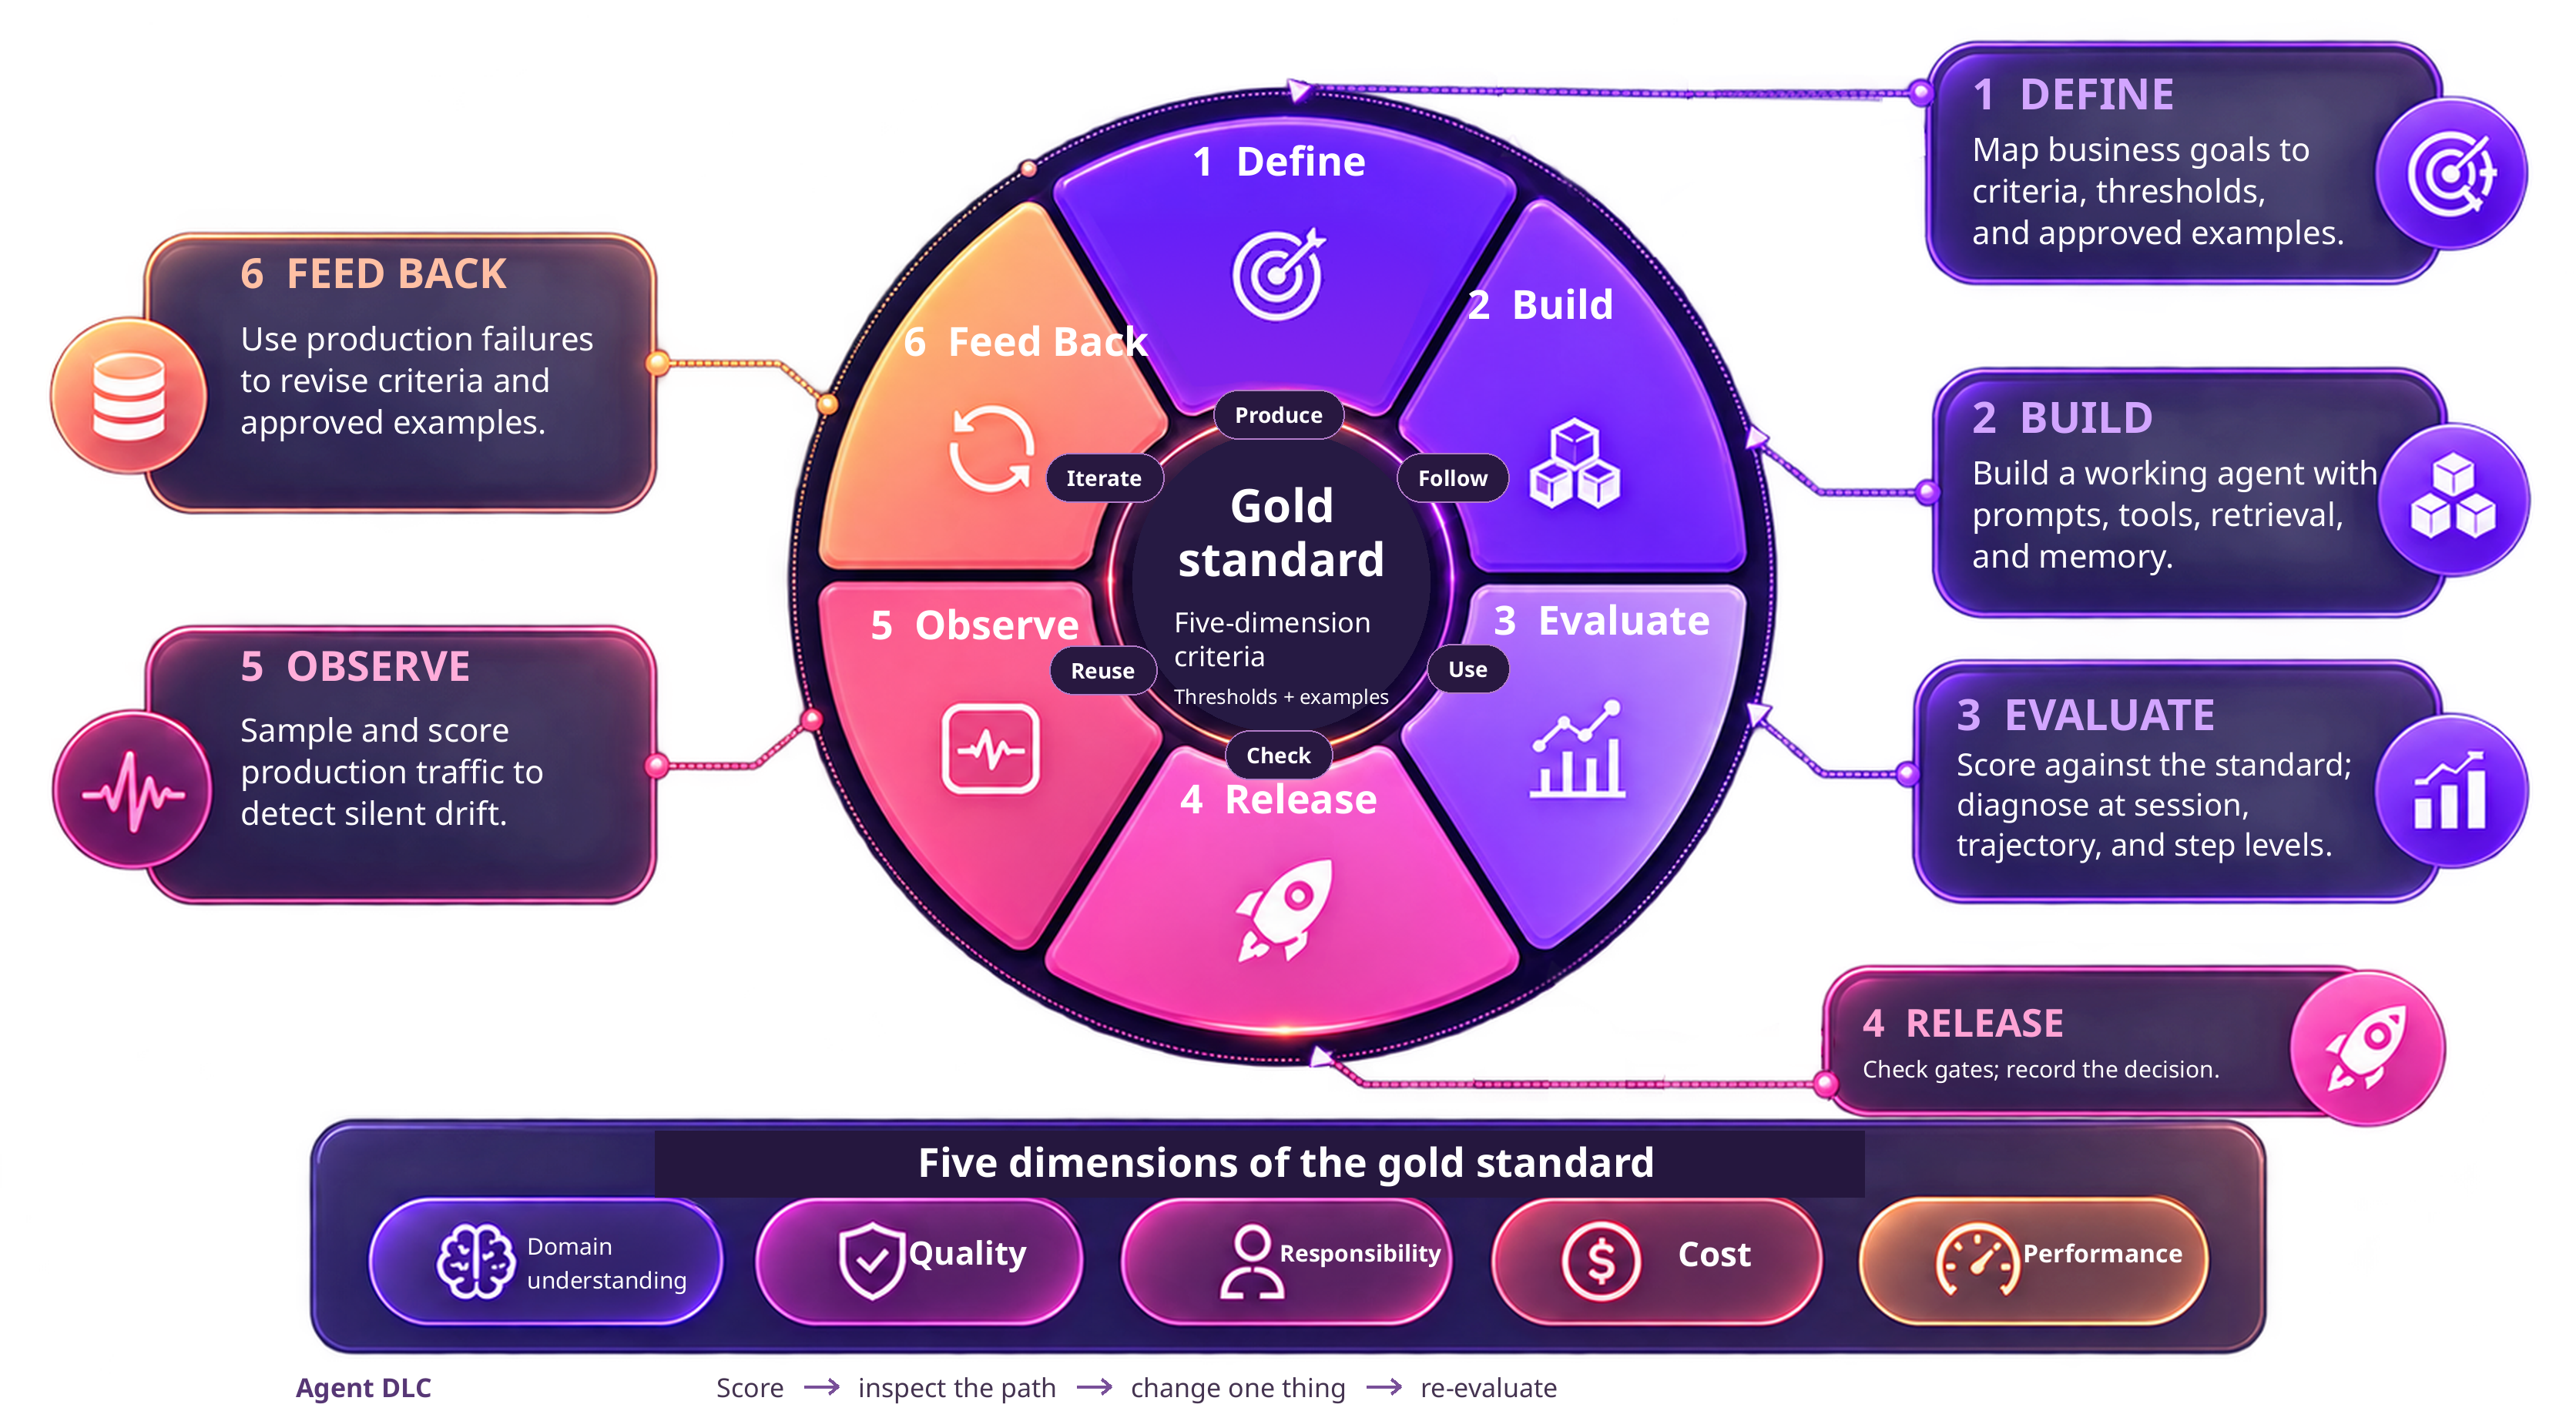
In an article titled "From prototype to production: Engineering agents with Agent DLC" published on November 12, 2026, AWS Machine Learning addressed common hurdles in agent deployment. The publication noted that projects often stall between demonstration and full release. This slowdown occurs because engineering teams frequently lack a standardized, repeatable approach to evaluate how well an agent performs.
The inability to measure quality makes it difficult for teams to assess whether recent system updates resulted in positive changes. Building reliable evaluation frameworks alongside agent software helps ensure that code modifications lead to verifiable progress. Without clear metrics to track improvements, agent development risks getting stuck in an endless prototyping cycle.
Artificial intelligence agents often stall between initial prototype demos and final production releases. Teams struggle to move past the demonstration phase when they lack repeatable methods to measure agent performance. Without proper evaluation techniques, engineering teams cannot determine if recent updates improved an agent.
For more details please read the original article at AWS Machine Learning.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.