HippoRAG: Neurobiologically inspired RAG using Amazon Bedrock, Amazon Neptune, and personalized PageRank
AWS Machine Learning published a demonstration on implementing HippoRAG within an Amazon Web Services infrastructure for enterprise-scale applications. The solution integrates Amazon Bedrock for large language model capabilities, Amazon Neptune for graph database needs, Amazon Neptune Analytics for algorithms like "Personalized PageRank", and Amazon Titan Embeddings for vector representations. This setup illustrates how neurobiologically inspired retrieval-augmented generation can be deployed using cloud native services.
Key Takeaways
- AWS Machine Learning has outlined an architectural deployment for HippoRAG, a neurobiologically inspired retrieval-augmented generation method.
Designed for deployment at enterprise scale, the system leverages cloud services to manage both graph structures and vector search functions.
- To achieve this, the workflow combines Amazon Bedrock for large language model features with Amazon Titan Embeddings to generate vector representations of data.
The graph processing components rely on Amazon Neptune to deliver standard graph database functionality.
- Additionally, Amazon Neptune Analytics executes complex graph algorithms, specifically incorporating "Personalized PageRank" to optimize information retrieval.
Building such hybrid architectures helps developers understand how combining knowledge graphs with vector embeddings can refine search context in retrieval-augmented generation systems.
- HippoRAG offers a neurobiologically inspired retrieval-augmented generation framework designed for enterprise-scale applications.
The implementation uses Amazon Bedrock to provide large language model capabilities alongside Amazon Titan Embeddings for vector representations.
- Amazon Neptune serves as the graph database, while Amazon Neptune Analytics handles algorithms such as "Personalized PageRank".
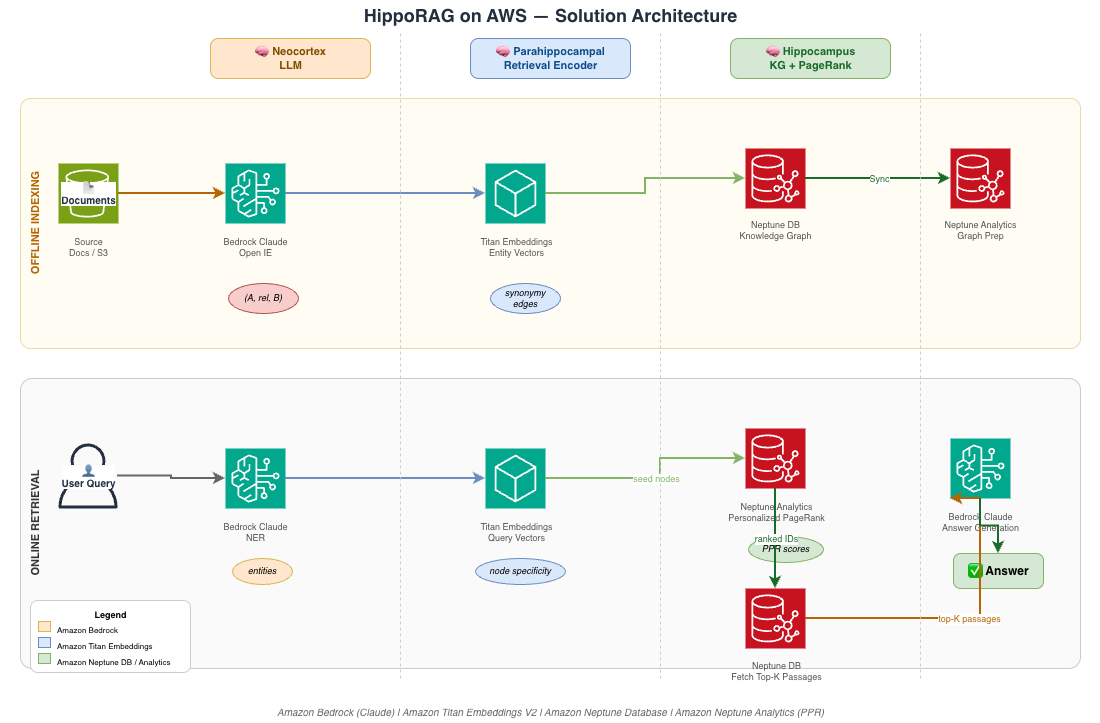
AWS Machine Learning has outlined an architectural deployment for HippoRAG, a neurobiologically inspired retrieval-augmented generation method. Designed for deployment at enterprise scale, the system leverages cloud services to manage both graph structures and vector search functions. To achieve this, the workflow combines Amazon Bedrock for large language model features with Amazon Titan Embeddings to generate vector representations of data.
The graph processing components rely on Amazon Neptune to deliver standard graph database functionality. Additionally, Amazon Neptune Analytics executes complex graph algorithms, specifically incorporating "Personalized PageRank" to optimize information retrieval. Building such hybrid architectures helps developers understand how combining knowledge graphs with vector embeddings can refine search context in retrieval-augmented generation systems.
HippoRAG offers a neurobiologically inspired retrieval-augmented generation framework designed for enterprise-scale applications. The implementation uses Amazon Bedrock to provide large language model capabilities alongside Amazon Titan Embeddings for vector representations. Amazon Neptune serves as the graph database, while Amazon Neptune Analytics handles algorithms such as "Personalized PageRank".
For more details please read the original article at AWS Machine Learning.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.