Up to 30x More Work Per Watt: NVIDIA Vera Rubin NVL72 Sets a New Efficiency Standard for AI Agents
NVIDIA has released performance data showing that its Vera Rubin NVL72 systems achieve up to 30x higher throughput per megawatt compared to the NVIDIA GB300 NVL72. Measured using the SemiAnalysis AgentX workload, the new architecture also cuts token expenses by up to 35x. These improvements aim to meet the heavy energy and context demands of autonomous agent workflows.
Key Takeaways
- New performance measurements from NVIDIA indicate that its Vera Rubin NVL72 platform generates up to 30x higher throughput per megawatt than the NVIDIA GB300 NVL72.
Evaluated using recorded coding sessions from the SemiAnalysis AgentX workload, the system also reduces token costs by up to 35x.
- Data from OpenRouter highlights that agentic AI tasks consume 15x more tokens than simple chat requests because autonomous workflows continually query databases, spawn sub-agents, and expand context lengths across multiple reasoning steps.
The efficiency gains measured on models such as DeepSeek V4 Pro stem from hardware codesign and power management features like NVIDIA DSX MaxLPS technologies, which can provision up to 40% more GPUs inside a fixed megawatt budget.
- Earlier generations like the GB300 NVL72 already provided 15x higher throughput per megawatt compared to the NVIDIA Hopper architecture.
These metrics illustrate how computing architecture must adapt past individual prompt requests to sustain continuous, multi-step agent operations within strict physical power limits.
- NVIDIA Vera Rubin NVL72 delivers up to 30x higher throughput per megawatt than NVIDIA GB300 NVL72 on agentic workloads.
According to OpenRouter data, agentic AI tasks generate 15x more tokens than typical chat queries due to repeated reasoning steps and tool calls.
- NVIDIA DSX MaxLPS technology enables facilities to deploy up to 40% more GPUs within a single megawatt power budget.
Stats & Key Facts
- #Measured using the SemiAnalysis AgentX workload, the new architecture also cuts token expenses by up to 35x.
- #Evaluated using recorded coding sessions from the SemiAnalysis AgentX workload, the system also reduces token costs by up to 35x.
- #Data from OpenRouter highlights that agentic AI tasks consume 15x more tokens than simple chat requests because autonomous workflows continually query databases, spawn sub-agents, and expand context lengths across multiple reasoning steps.
- #The efficiency gains measured on models such as DeepSeek V4 Pro stem from hardware codesign and power management features like NVIDIA DSX MaxLPS technologies, which can provision up to 40% more GPUs inside a fixed megawatt budget.
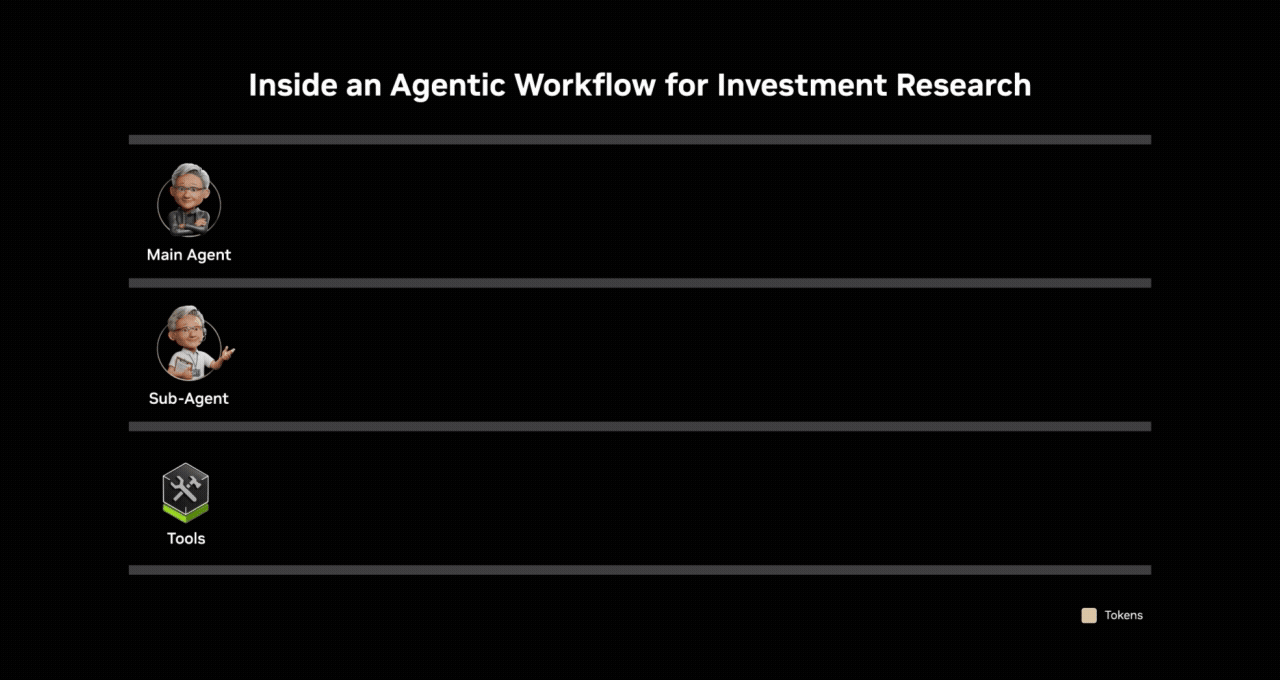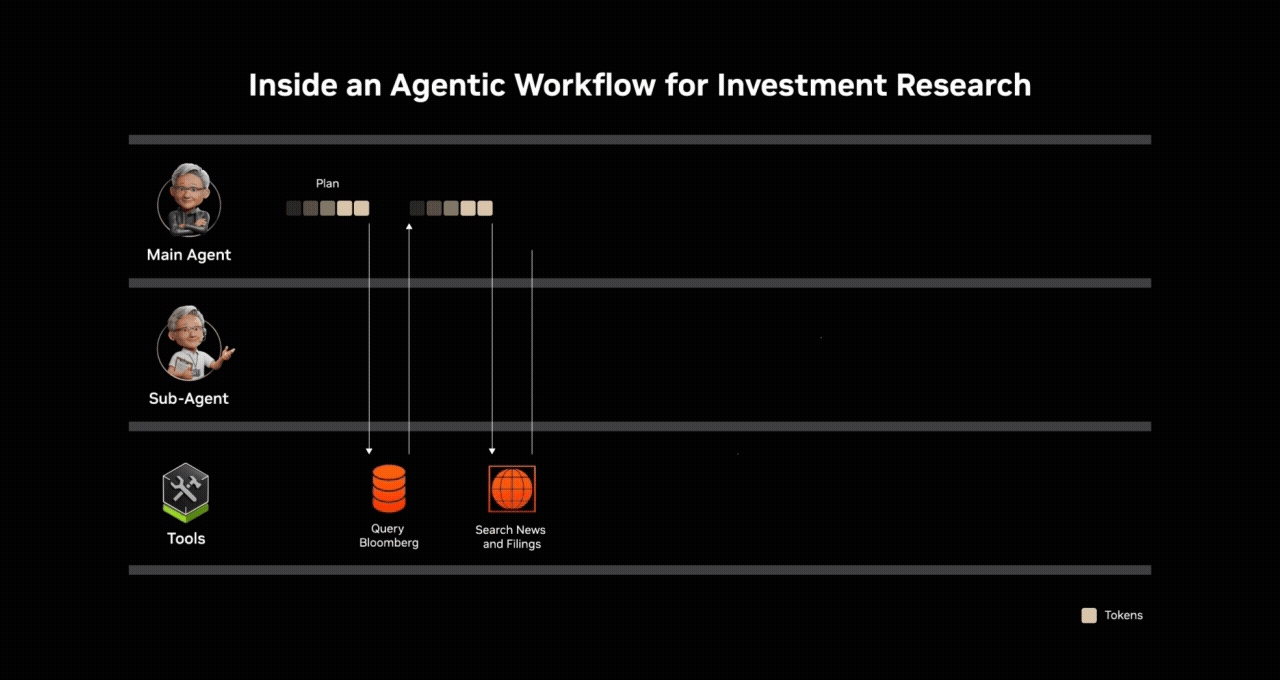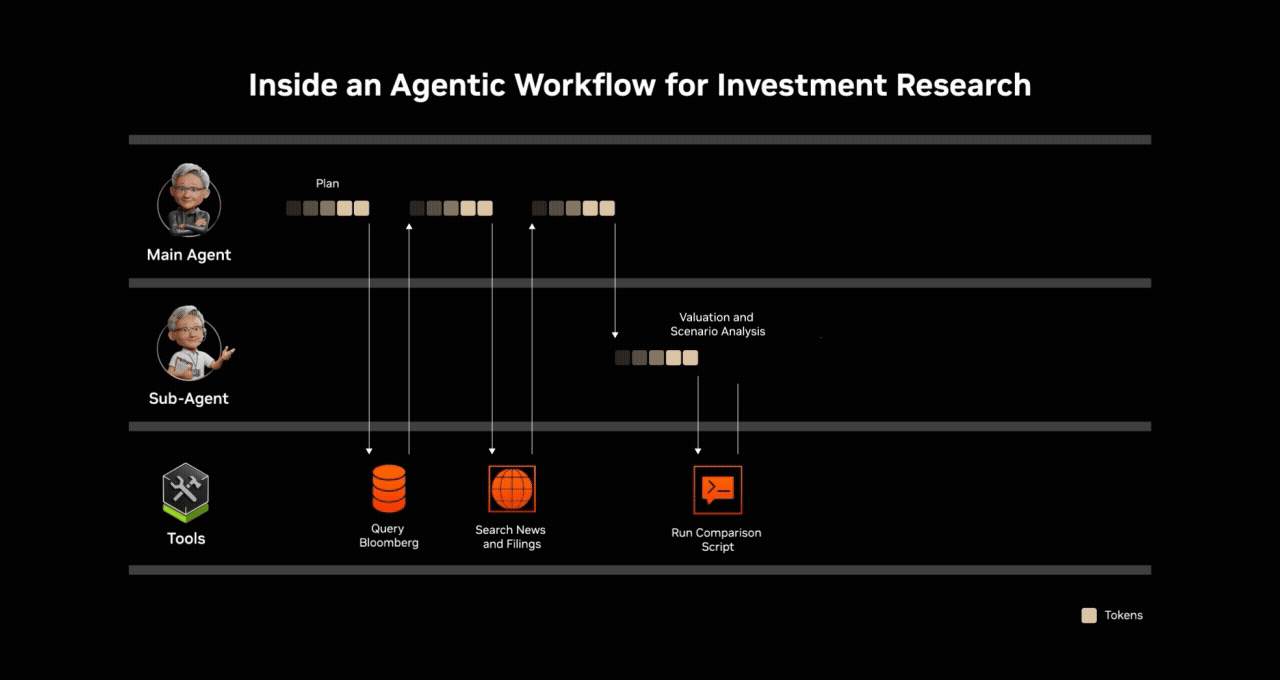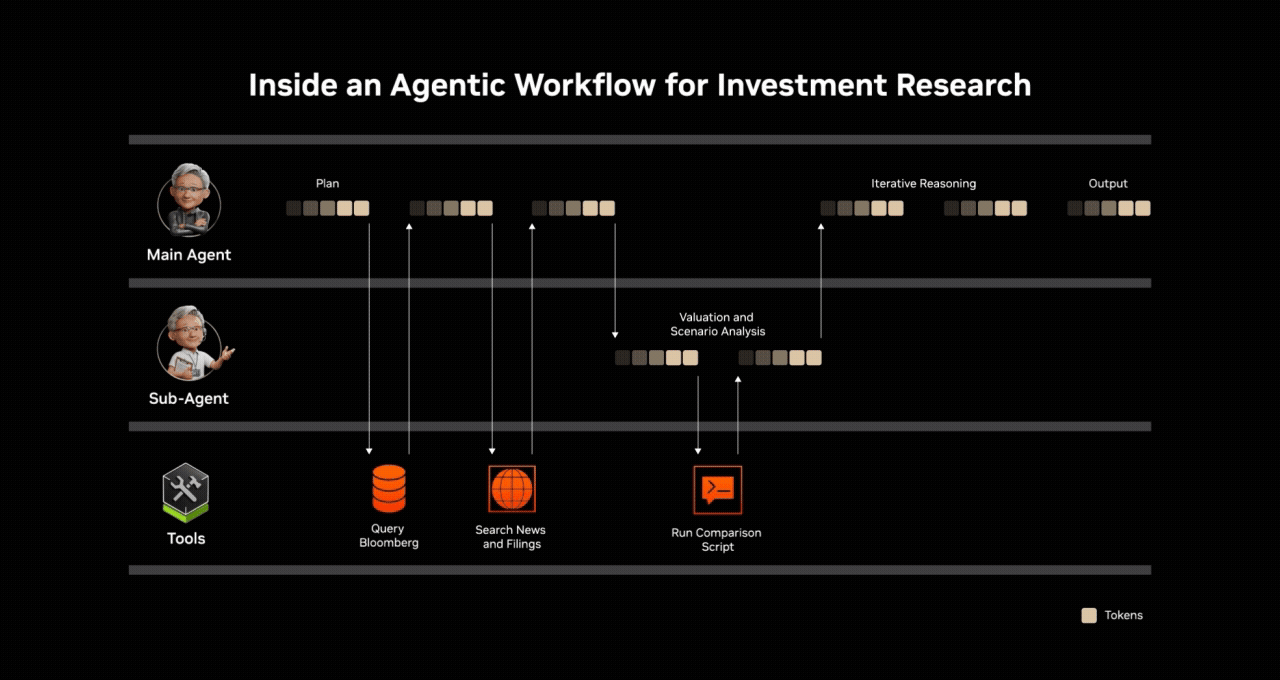
New performance measurements from NVIDIA indicate that its Vera Rubin NVL72 platform generates up to 30x higher throughput per megawatt than the NVIDIA GB300 NVL72. Evaluated using recorded coding sessions from the SemiAnalysis AgentX workload, the system also reduces token costs by up to 35x. Data from OpenRouter highlights that agentic AI tasks consume 15x more tokens than simple chat requests because autonomous workflows continually query databases, spawn sub-agents, and expand context lengths across multiple reasoning steps.
The efficiency gains measured on models such as DeepSeek V4 Pro stem from hardware codesign and power management features like NVIDIA DSX MaxLPS technologies, which can provision up to 40% more GPUs inside a fixed megawatt budget. Earlier generations like the GB300 NVL72 already provided 15x higher throughput per megawatt compared to the NVIDIA Hopper architecture. These metrics illustrate how computing architecture must adapt past individual prompt requests to sustain continuous, multi-step agent operations within strict physical power limits.
NVIDIA Vera Rubin NVL72 delivers up to 30x higher throughput per megawatt than NVIDIA GB300 NVL72 on agentic workloads. According to OpenRouter data, agentic AI tasks generate 15x more tokens than typical chat queries due to repeated reasoning steps and tool calls. The Vera Rubin NVL72 system reduces token processing costs by up to 35x compared to the GB300 NVL72 baseline.
For more details please read the original article at NVIDIA Blog.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.