With Groq 3 LPX in Full Production, NVIDIA Extends Vera Rubin Inference for Agents
NVIDIA has launched full production for its Groq 3 LPX system to enhance token generation within its Vera Rubin NVL72 infrastructure for autonomous agents. In a benchmark test using Gemma 4 31B across 100,000-token long-context scenarios, the architecture achieved 3,400 output tokens per second. Partners including SpaceXAI, CoreWeave, and Nebius are adopting various components of the new platform to expand their cloud capabilities.
Key Takeaways
- NVIDIA announced that its Groq 3 LPX system is in full production, extending the Vera Rubin NVL72 platform to accelerate token creation for agentic AI applications.
Tested in an Artificial Analysis benchmark using Gemma 4 31B, the setup processed 3,400 output tokens per second during 100,000-token long-context evaluations.
- Several technology providers have already begun integrating Vera Rubin platform technologies into their production systems.
Nebius became the initial cloud provider to incorporate NVIDIA Groq 3 LPX into its infrastructure, aiming to improve real-time interactive capabilities.
- As artificial intelligence tasks transition from model training to active reasoning, hardware infrastructure must adapt to process larger context windows efficiently.
Modern agentic workflows rely on high throughput and unified architecture rather than isolated individual chips.
- NVIDIA announced that its NVIDIA Groq 3 LPX rack-scale system is now in full production for agentic AI workloads.
In an Artificial Analysis benchmark with Gemma 4 31B, the platform reached 3,400 output tokens per second for 100,000-token long-context tasks.
- SpaceXAI selected NVIDIA Vera CPUs for its next generation of agentic AI, while CoreWeave deployed Spectrum-X Multiplane.
Stats & Key Facts
- #In a benchmark test using Gemma 4 31B across 100,000-token long-context scenarios, the architecture achieved 3,400 output tokens per second.
- #Tested in an Artificial Analysis benchmark using Gemma 4 31B, the setup processed 3,400 output tokens per second during 100,000-token long-context evaluations.
- #In an Artificial Analysis benchmark with Gemma 4 31B, the platform reached 3,400 output tokens per second for 100,000-token long-context tasks.
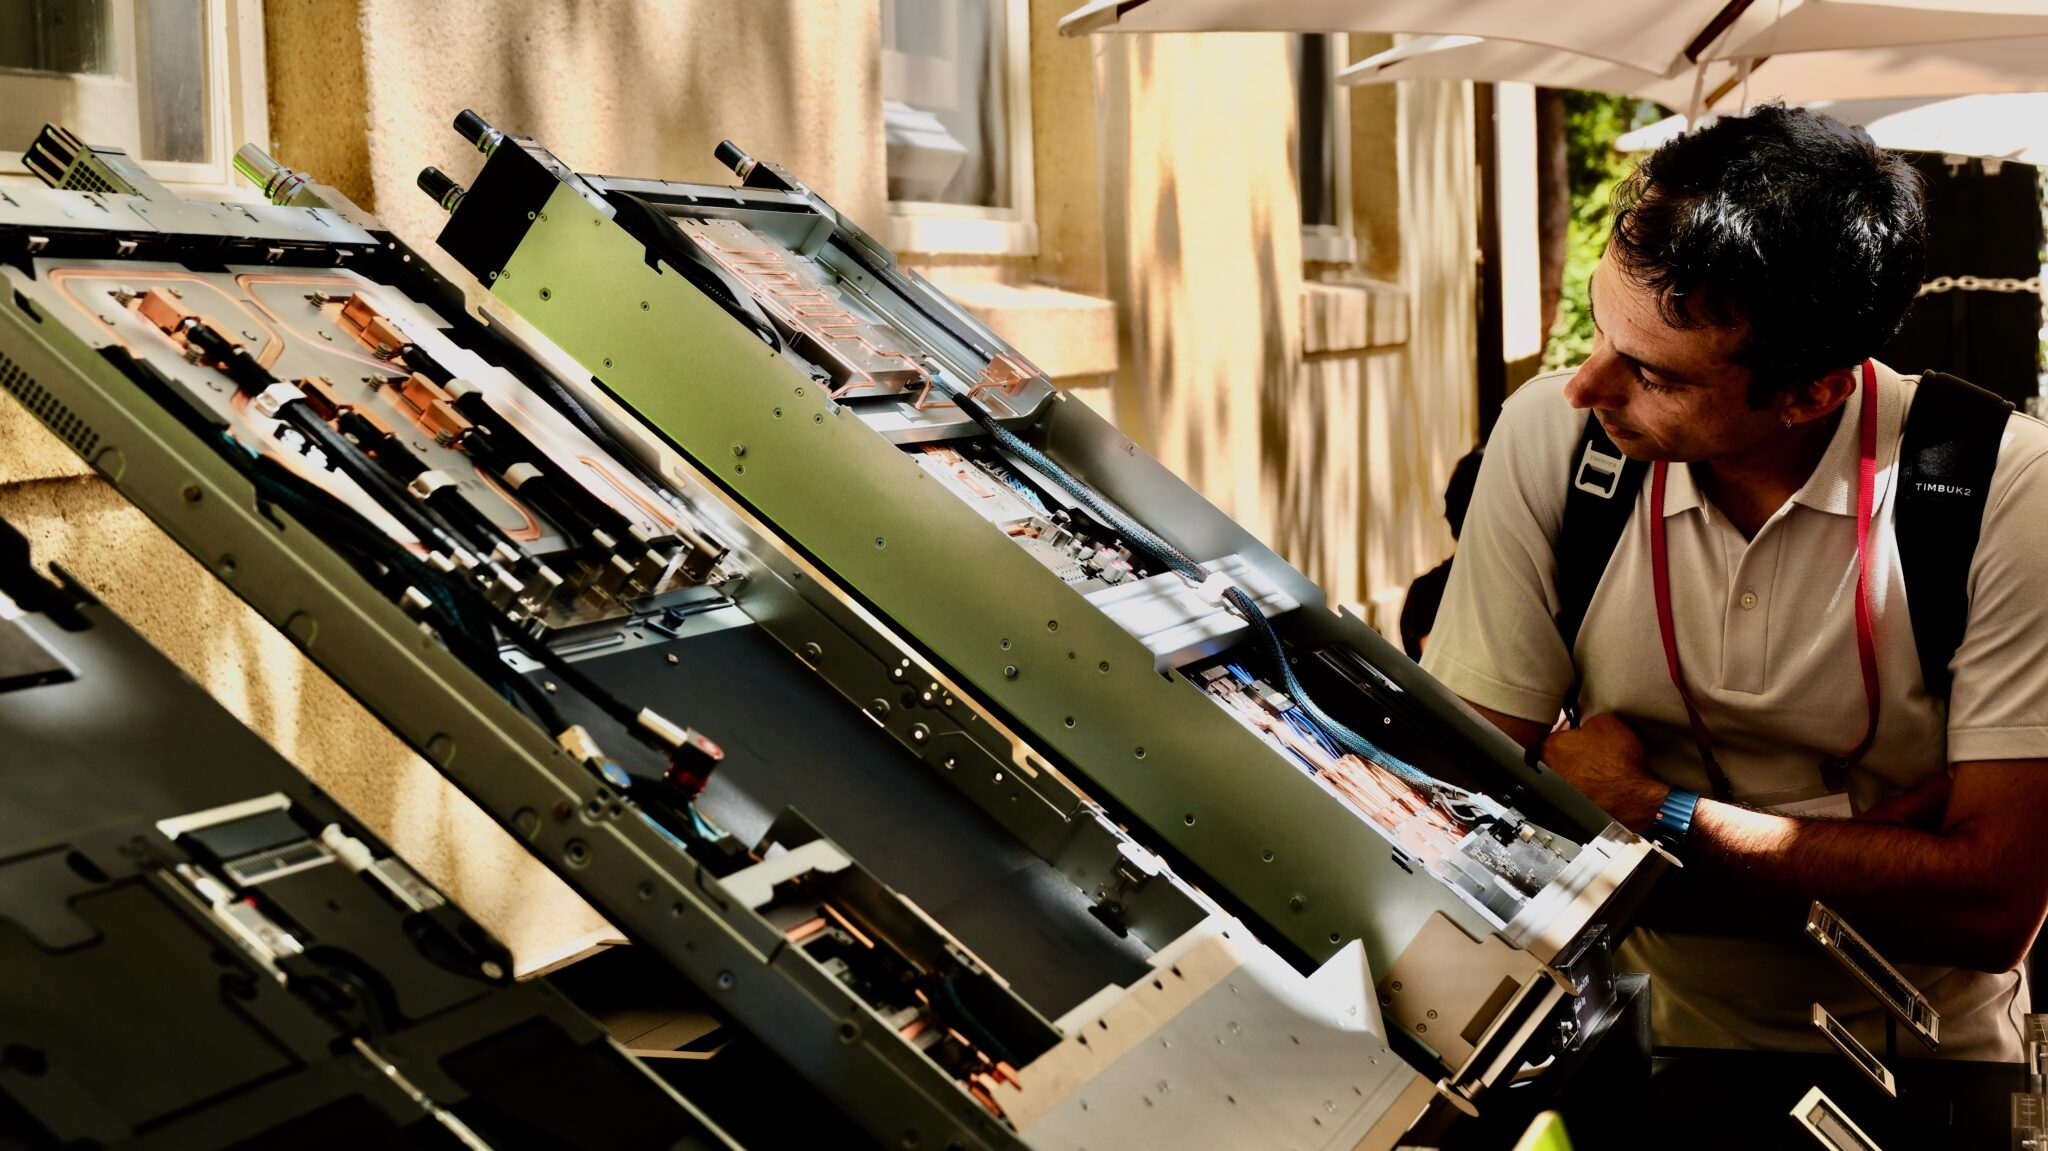
NVIDIA announced that its Groq 3 LPX system is in full production, extending the Vera Rubin NVL72 platform to accelerate token creation for agentic AI applications. Tested in an Artificial Analysis benchmark using Gemma 4 31B, the setup processed 3,400 output tokens per second during 100,000-token long-context evaluations. This speed represented a fourfold advantage over the closest competing platform, addressing the heavy computational demands of long-sequence reasoning.
Several technology providers have already begun integrating Vera Rubin platform technologies into their production systems. Nebius became the initial cloud provider to incorporate NVIDIA Groq 3 LPX into its infrastructure, aiming to improve real-time interactive capabilities. Additionally, SpaceXAI plans to utilize NVIDIA Vera CPUs for its upcoming agentic AI tools, and CoreWeave has implemented Spectrum-X Multiplane to connect server racks with parallel networking switches.
As artificial intelligence tasks transition from model training to active reasoning, hardware infrastructure must adapt to process larger context windows efficiently. Modern agentic workflows rely on high throughput and unified architecture rather than isolated individual chips. For hardware developers and software engineers, these updates highlight how tight integration across compute, networking, and token generation is becoming critical for complex multi-agent deployments.
NVIDIA announced that its NVIDIA Groq 3 LPX rack-scale system is now in full production for agentic AI workloads. In an Artificial Analysis benchmark with Gemma 4 31B, the platform reached 3,400 output tokens per second for 100,000-token long-context tasks. Cloud provider Nebius became the first AI cloud to integrate NVIDIA Groq 3 LPX into its token infrastructure.
For more details please read the original article at NVIDIA Blog.
Continue Learning
Comments
Comments appear only after moderation. Your email identifies your submission to the moderator and is never displayed here.
No approved comments yet.